

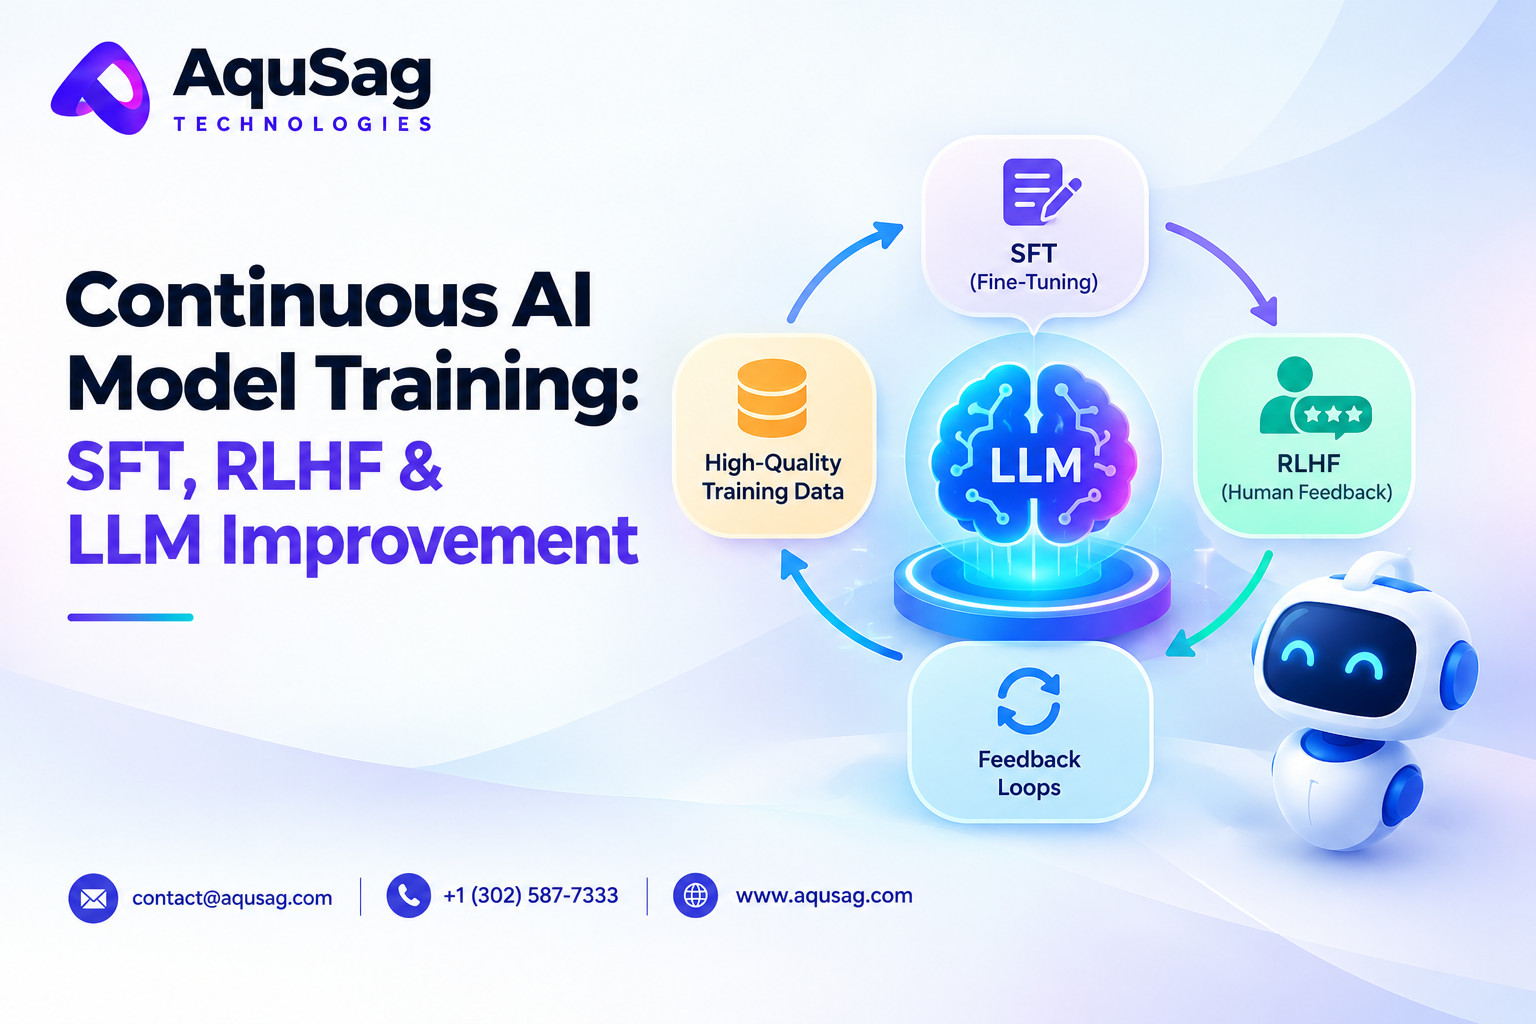
Continuous AI Model Training: SFT, RLHF & LLM Improvement
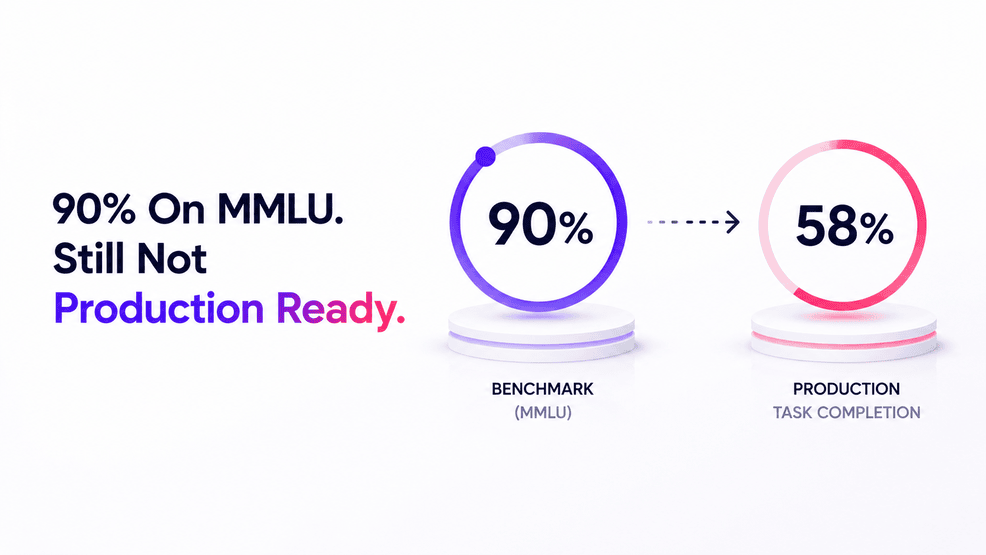
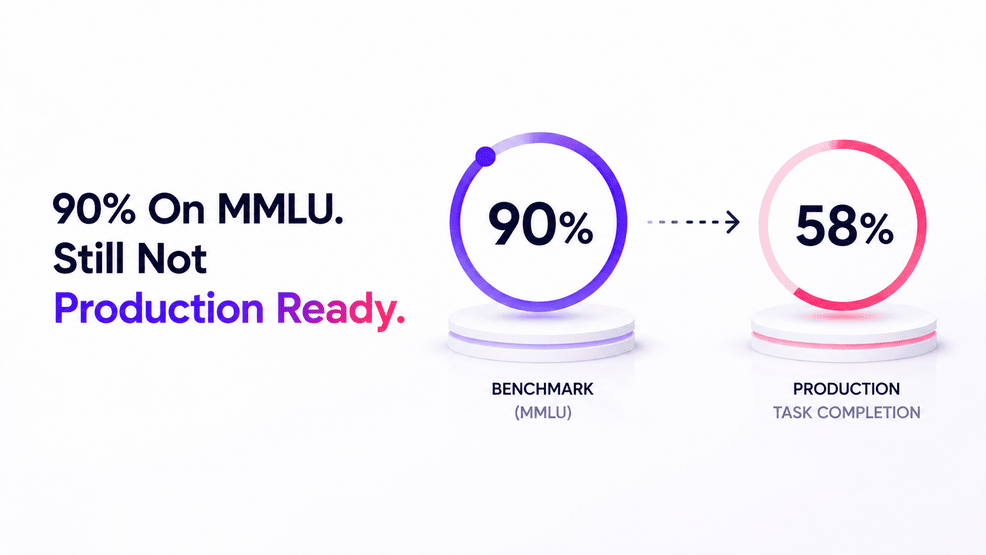
Learn how continuous AI model training improves LLM performance through Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), high-quality training data, and feedback loops. Discover AI post-training strategies to improve model accuracy, reliability, safety, and real-world performance.
https://aqusag.com/blog/aqusag....-technologies-blog-5
Like


Comment
Share